
What do we actually gain from using an LLM?
Preprint: https://arxiv.org/abs/2609.16793
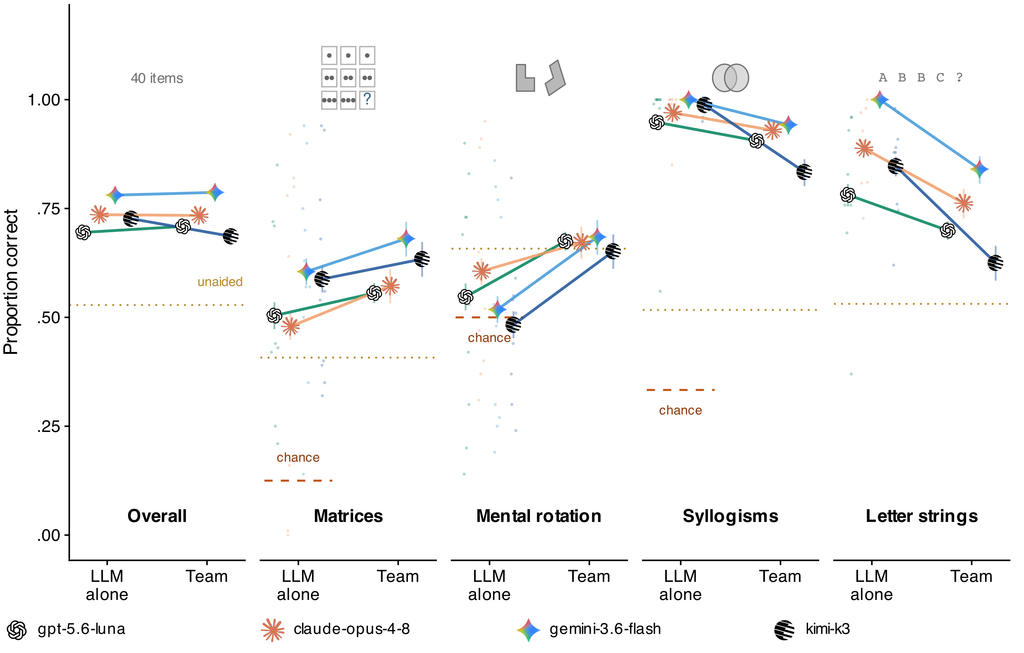
In our new preprint, 535 people solved 40 reasoning problems, alone or with GPT-5.6-Luna, Claude Opus 4.8, Gemini 3.6 Flash, or Kimi K3. We also tested each model on every problem 100 times to see how reliably it answered.
People benefited more on problems the AI handled well. The estimated break-even point for outperforming unaided reasoning was around 25% model accuracy.
Better AI performance also didn’t translate one-for-one into better human performance. In one comparison across problems, a 50-point difference in model accuracy corresponded to about 26 points for people using it.
People often accepted incorrect advice, and feeling confident after consulting AI was no guarantee of being right.
Stronger models matter. So do interactions that help people question advice, compare answers, and keep their own reasoning in play. We should measure not just what AI can do, but what people can do with it.